
Robots.txt best practice comes down to a short file with two decisions in it. Let Google, Bing and the AI search bots crawl everything that matters. Keep them out of junk URLs like admin pages, internal search results and carts. List your sitemap. Never use the file to hide a page. Everything else on this page explains how to do that on your own site in about 15 minutes, and how to check it worked.
Here is what a good small-business file looks like, line by line:
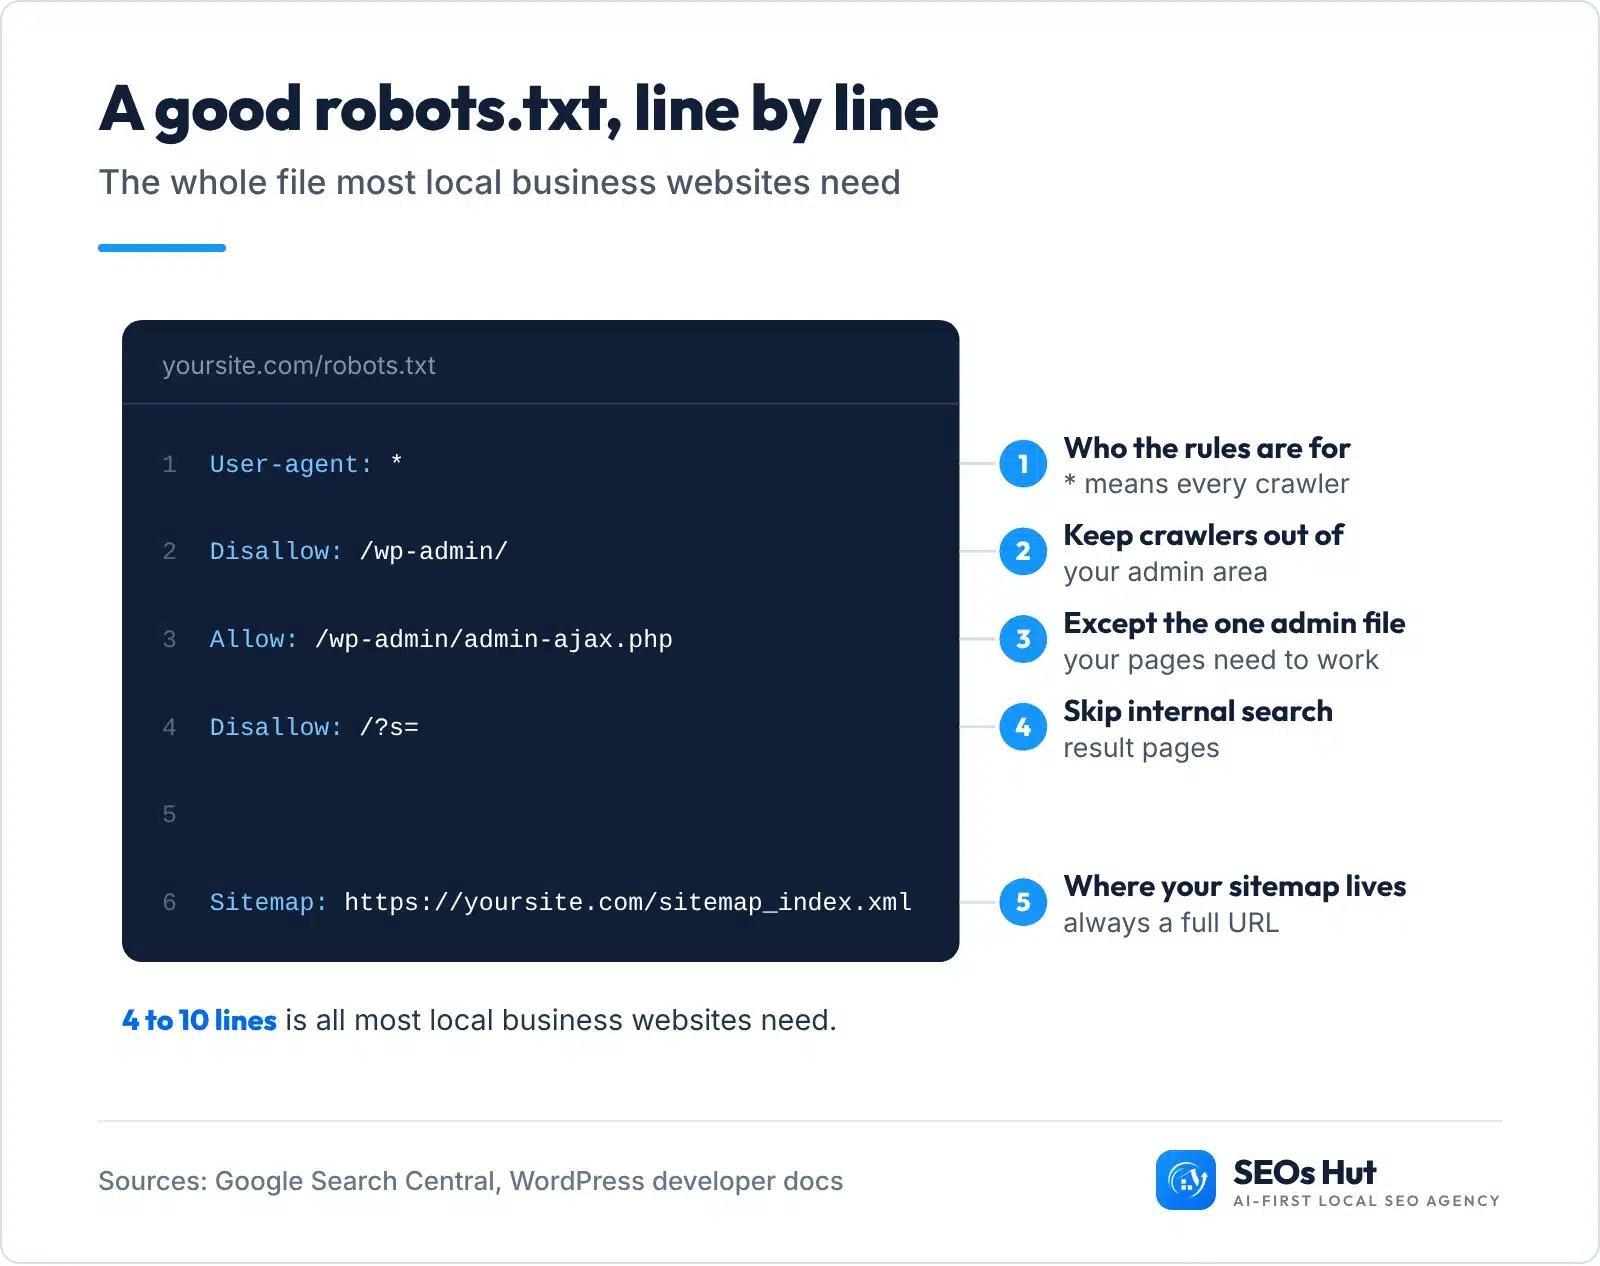
That is the whole job for most local businesses: four to ten lines. When we checked 100 real local business websites (results below), the typical file had about five rules. The danger is not a short file. It is one wrong line: a stray slash that hides your site from Google, a blocked script folder, or an AI rule that quietly keeps you out of ChatGPT search.
Short on time? Skip to the free robots.txt builder and tester, or grab the one-page checklist with copy-paste templates (PDF).
What is robots.txt?
A robots.txt file is a plain text file at the root of your website (for example yoursite.com/robots.txt) that tells crawlers which URLs they may and may not request. Google, Bing, ChatGPT, Claude and Perplexity all read it before they crawl.
Three facts change how you should use it:
- It controls crawling, not indexing. Google says robots.txt “is not a mechanism for keeping a web page out of Google”. A blocked URL can still show up in results if other pages link to it.
- It is a request, not a lock. The official standard, RFC 9309 (published September 2022), says plainly that these rules “are not a form of access authorization.” Polite bots obey. Bad bots ignore it, and anyone can read the file.
- It only works in one place. According to Google’s robots.txt specification, the file must sit in the top-level directory, and a file on a subdomain only covers that subdomain. So
shop.yoursite.comneeds its own.
Does robots.txt help SEO?
Mostly it protects your SEO rather than boosting it. A clean file stops Google wasting visits on endless filter or search-result URLs, and points crawlers to your sitemap. A bad file can wipe you out of search. No ranking gain comes from the file itself.
You don’t strictly need one. Google treats a missing file (a 404) “as if a valid robots.txt file didn’t exist” and crawls everything. The real risk is a server error: if your robots.txt returns a 5xx error, Google stops crawling the site for the first 12 hours and keeps retrying, then falls back to the last good copy for up to 30 days. A broken file is worse than no file.
Plenty of big sites skip it. Cloudflare reported in July 2025 that only about 37% of the top 10,000 domains had a robots.txt file. Small local sites are the opposite, because WordPress, Shopify and most builders create one for you. That is exactly what we found.
We checked the robots.txt files of 100 local business websites
On 9 November 2026 we took the top Google Maps results for “plumber Phoenix AZ” (50 websites) and “dentist Austin TX” (50 websites), fetched every robots.txt, and read it the way Google does: longest matching rule wins, wildcards included. Then we tested the homepage against 13 crawlers, from Googlebot to GPTBot.

What stood out:
- Nobody blocked Google. 96 of the 100 sites had a working file with rules, and none of the 96 blocked Googlebot or Bingbot. (Of the other four, one had no file at all, one was empty, one had rules with no User-agent line, and one served a web page instead of a text file.)
- AI bots are mostly welcome by default. 86 of 96 files (90%) let all 13 crawlers in. Only 18 files mention any AI bot by name.
- Training blocks are usually a hosting setting, not a decision. 10 files (10%) block GPTBot, and 8 of those 10 carry Cloudflare’s “Content-Signal” text, the wording its managed robots.txt adds. Nine of the ten still let the AI search bots in, which is the sensible split.
- Old bot names give a false sense of control. 14 files block “anthropic-ai” or “Claude-Web”. Those names are not on Anthropic’s current crawler list, and 5 of those files never mention ClaudeBot, so ClaudeBot can still crawl them.
- Dead rules are common. 15 files (16%) use crawl-delay, which Google ignores, and 5 of them put it above any User-agent line, where it belongs to no group at all. Three block WordPress’s
/wp-includes/folder, which holds scripts Google needs to see pages properly. - Sitemap lines mostly work. 87 files (91%) list a sitemap, but at least 3 of those lines point nowhere useful: a relative URL, a domain that no longer loads, and a web page instead of XML.
The lesson: you don’t need anything clever. You need the defaults kept clean, one deliberate AI choice, and a check after every change. That’s the rest of this guide.
Robots.txt best practices: the 8 rules that matter
1. Keep one file, at the root, per host
The file lives at https://yoursite.com/robots.txt, named in lowercase. A copy in a subfolder does nothing. Each subdomain and each protocol needs its own file. Google enforces a 500 KiB size limit, which a small business will never get near unless something is generating rules automatically.
2. Start from your platform’s default
Your platform already writes a decent file. Edit it rather than replacing it:
| Platform | What you get by default | How you change it |
|---|---|---|
| WordPress | Blocks /wp-admin/, allows admin-ajax.php, and has listed your sitemap since version 5.5 |
Yoast or Rank Math file editor, or upload a real robots.txt file to the site root (it replaces the virtual one) |
| Shopify | A generated file that, in Shopify’s words, “works for most stores” | Create the robots.txt.liquid theme template. Keep the default Liquid and add your extra groups at the bottom |
| Wix | A generated file | The Robots.txt Editor in your SEO dashboard (it has a reset button) |
| Squarespace | A generated file | Squarespace manages the file. Settings, then Crawlers, has a checkbox to block known AI crawlers |
3. Block crawl traps, never pages you want hidden
Good things to block: internal search results (/?s= on WordPress, /search elsewhere), cart and checkout steps, endless filter combinations, and your admin area. These waste crawler visits and never belong in search.
Bad things to block: a thank-you page, an old service page, a private PDF, anything you want removed from Google. This is the most common mistake on the internet, and here is why it backfires:

Google spells it out: for the noindex rule to work, “the page or resource must not be blocked by a robots.txt file”. So to hide a page, let Google crawl it and add a noindex tag. For truly private content, use a password. To check whether a page is in Google right now, use our free Google Index Checker.
4. Never block CSS, JavaScript or images your pages need
Google views pages like a browser does. Its JavaScript guide says “Google Search won’t render JavaScript from blocked files or on blocked pages.” On WordPress that means: never block /wp-includes/ or /wp-content/. Three files in our study did exactly that.
5. List your sitemap as a full URL
Add one line per sitemap, anywhere in the file: Sitemap: https://yoursite.com/sitemap_index.xml. Google says it “must be a fully qualified URL, including the protocol and host”, so /sitemap.xml on its own does not count. Not sure where your sitemap lives? Our guide on how to find a website’s sitemap shows every common location, and the Sitemap Checker confirms it loads.
6. Know how Google picks between rules
Four rules from Google’s specification explain almost every surprise:
- Longest rule wins. With
Disallow: /wp-admin/andAllow: /wp-admin/admin-ajax.php, the Allow is longer, so that one file stays crawlable. - Ties go to Allow. When an Allow and a Disallow match with the same length, Google uses the least restrictive rule.
- Paths are case-sensitive.
Disallow: /Private/does not block/private/. - Two wildcards only.
*matches anything,$means “ends here”.Disallow: /*.pdf$blocks every URL ending in .pdf.
A bot also follows only the most specific group that names it. If you add a User-agent: Googlebot group, Googlebot ignores everything under User-agent: *, so repeat any shared rules inside it.
7. Delete the rules Google ignores
Google stopped supporting noindex in robots.txt on 1 September 2019, along with nofollow, and it has never supported crawl-delay. Bing does honour crawl-delay, as a time window of 1 to 30 seconds, and Anthropic says its bots support it too. If your server copes fine, delete it. If you keep it, put it inside a User-agent group, never at the top of the file.
8. Test every change, then tell Google
Google caches your file for up to 24 hours, and OpenAI and Perplexity say their systems take about the same time to adjust. After any edit: open yoursite.com/robots.txt in a browser, run it through the tester below, then use “Request a recrawl” in Search Console’s robots.txt report.
Robots.txt for AI crawlers: search bots vs training bots
This is the decision most guides get wrong. AI companies run separate bots for separate jobs, and blocking the wrong one can remove you from AI answers without stopping training at all.
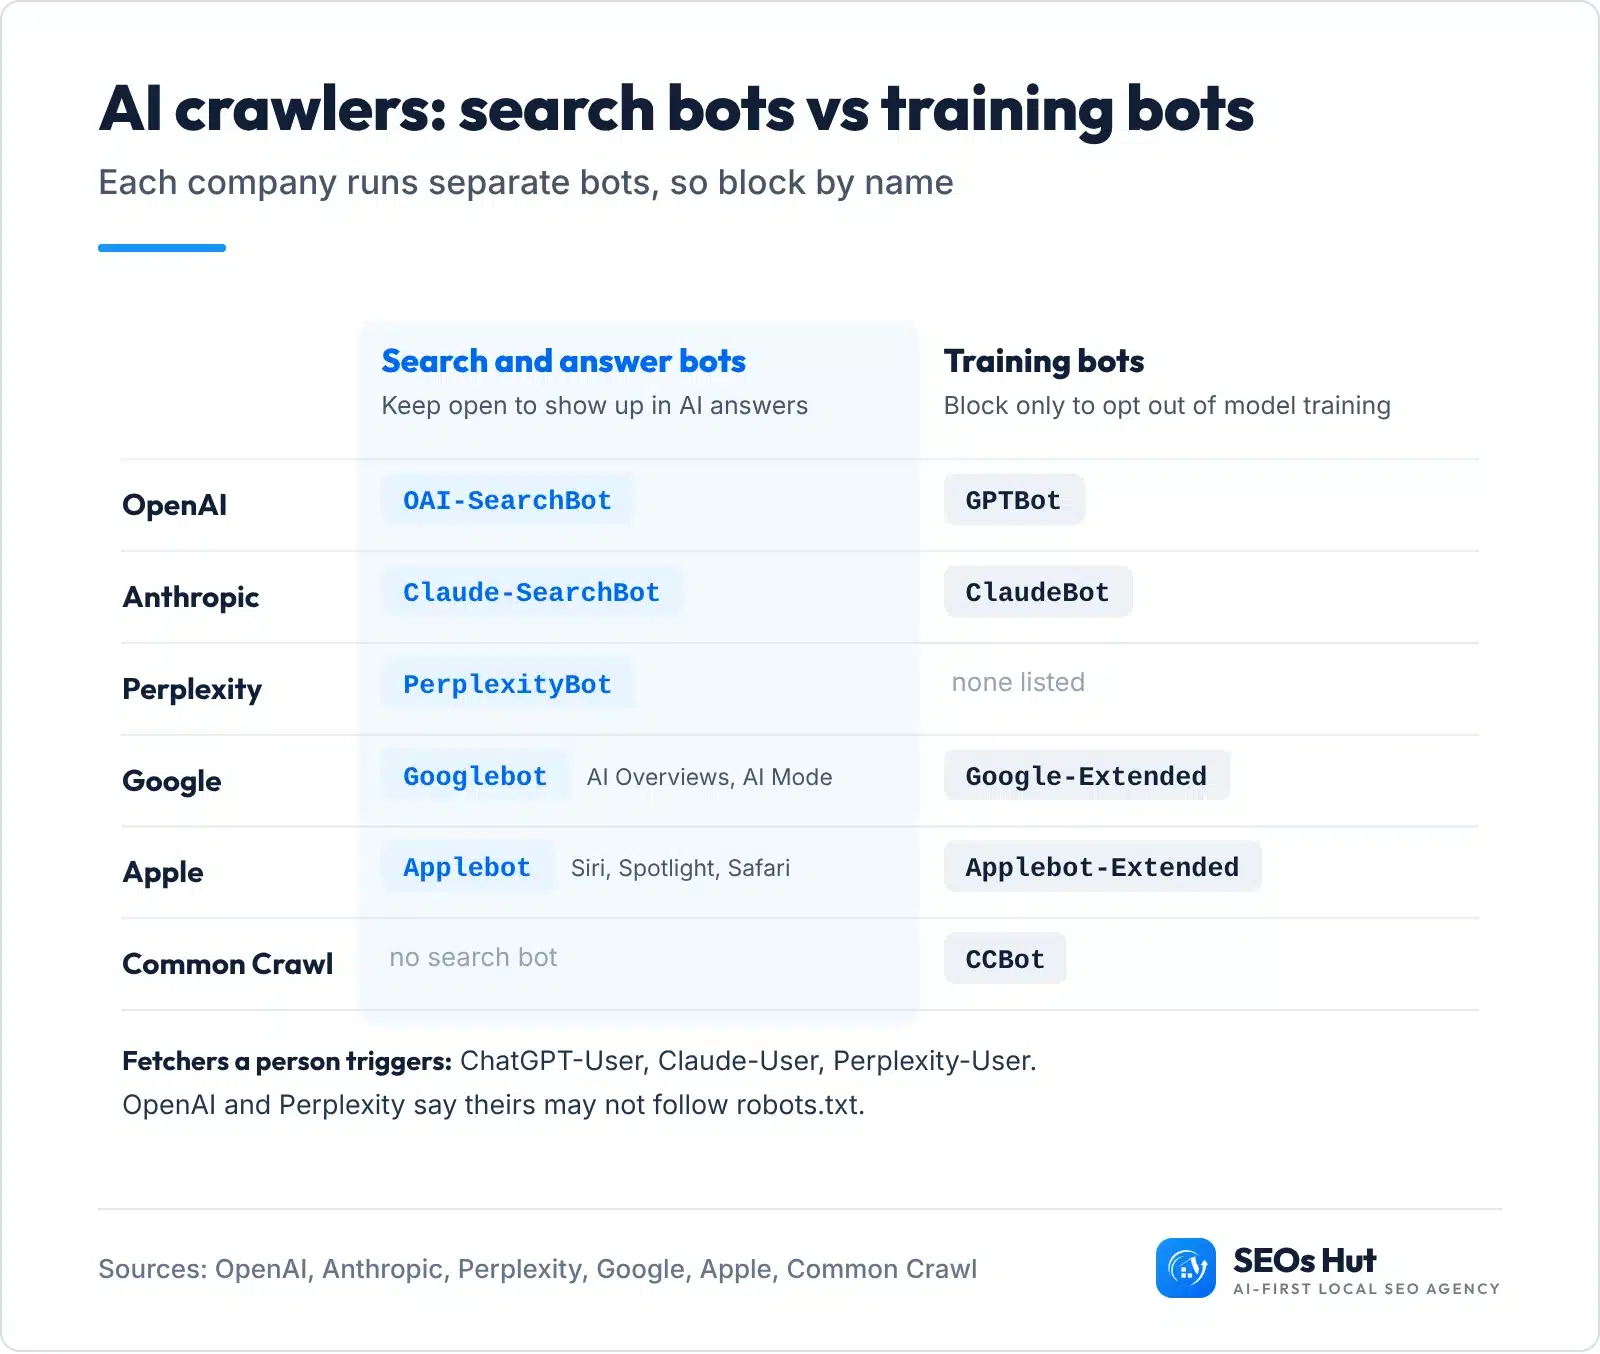
What each company says in its own documentation:
- OpenAI: GPTBot collects training data. OAI-SearchBot powers ChatGPT search, and “Sites that are opted out of OAI-SearchBot will not be shown in ChatGPT search answers”. ChatGPT-User visits pages when a person asks, and “robots.txt rules may not apply.”
- Anthropic: ClaudeBot collects training data, Claude-SearchBot improves search results, and Claude-User fetches pages for a user’s question. Anthropic warns that blocking Claude-User stops its system retrieving your content for those questions.
- Perplexity: PerplexityBot “is not used to crawl content for AI foundation models”. It exists to show and link your site in Perplexity answers. Perplexity-User “generally ignores robots.txt rules” because a person asked for the page.
- Google: Google-Extended controls Gemini training and grounding, and Google says it “does not impact a site’s inclusion in Google Search nor is it used as a ranking signal”. For AI Overviews and AI Mode, the control is your normal Googlebot rules.
- Apple and Common Crawl: blocking Applebot-Extended opts you out of Apple’s model training, while your content “will remain discoverable through Spotlight, Siri, and Safari”. CCBot is Common Crawl’s crawler, and it sits on Squarespace’s list of AI crawlers too.
So which should a local business pick? If you want customers to find you in ChatGPT, Perplexity and Google’s AI answers, keep every search bot open. Blocking training bots is a values call, not an SEO one. Cloudflare’s June 2025 data shows why some owners make it: Google crawled sites about 14 times for every referral, OpenAI 1,700 times and Anthropic 73,000 times. If you block training, block it by name and leave the search bots alone:
# Let AI search bots find you
User-agent: OAI-SearchBot
User-agent: Claude-SearchBot
User-agent: PerplexityBot
Allow: /

# Opt out of AI model training
User-agent: GPTBot
User-agent: ClaudeBot
User-agent: Google-Extended
User-agent: Applebot-Extended
User-agent: CCBot
Disallow: /
Two honest limits. Robots.txt does not remove anything already collected, and bots that fetch a page because a user asked may not read it at all. If you want to go further, an llms.txt file is a separate, optional signal, and our free AI Crawler Access Checker shows which AI bots can reach your site today.
Robots.txt examples you can copy
Swap yoursite.com for your domain. Each one is a complete file.
WordPress (most local business sites):
User-agent: *
Disallow: /wp-admin/
Allow: /wp-admin/admin-ajax.php
Disallow: /?s=
Disallow: /search/

Sitemap: https://yoursite.com/sitemap_index.xml
Any other website (allow everything, list the sitemap):
User-agent: *
Disallow:

Sitemap: https://yoursite.com/sitemap.xml
Staging or test site (keep every crawler out):
User-agent: *
Disallow: /
Use the last one only on a copy of your site, never on the live one. Better still, put the staging site behind a password, because robots.txt is public and only a request.
Want to know where you stand before you edit anything? Run your domain through our free AI Crawler Access Checker to see which AI crawlers can reach your site, and if you have server logs, the AI Crawler Log Analyzer shows which bots actually visit. Free, no signup.
Free robots.txt builder and tester
Build a file for your platform, or paste any robots.txt and test a URL against 13 crawlers. It runs in your browser, so nothing is sent anywhere and there is no signup.
Your robots.txt
How to create and upload a robots.txt file
- See what you have now. Open
https://yoursite.com/robots.txtin your browser and copy the text somewhere safe as a backup. - Write the new version. Use the builder above or one of the examples. Keep it in a plain text editor (Notepad or TextEdit in plain-text mode), saved as
robots.txtin UTF-8. - Put it live. WordPress: in Yoast go to Yoast SEO, Tools, File editor; in Rank Math go to General Settings, Edit robots.txt; or upload the file to your site’s root folder in your host’s file manager. Shopify: edit
robots.txt.liquidin your theme code. Wix: SEO & GEO dashboard, Robots.txt Editor. Squarespace: Settings, Crawlers. - Test it. Reload
/robots.txtto confirm the new text shows, then paste it into the tester above and check your homepage, a service page and one blocked URL. - Tell Google. In Search Console, open the robots.txt report (Settings, then robots.txt under Crawling), confirm it fetched without errors, and click “Request a recrawl”.
- Check the AI side. Run your domain through the AI Crawler Access Checker to confirm the AI bots you want can get in.
How to fix “Blocked by robots.txt” in Search Console
This status means Google found the URL but your file told it not to crawl. First ask: should this page be in Google?
- Yes, it should rank: find the rule blocking it (paste your file and the URL into the tester above, which shows the exact line), remove or narrow that rule, then use URL Inspection and “Request indexing”.
- No, it’s junk (search results, filters, cart): nothing to fix. The report is just telling you the rule works.
- “Indexed, though blocked by robots.txt”: Google listed the URL without reading it. If you want it gone, remove the block, add a noindex tag, and let Google recrawl it. If you want it to rank, just remove the block.
If several important pages show up there, the problem is usually bigger than one line. Our guide to checking whether a page is indexed walks through the full diagnosis.
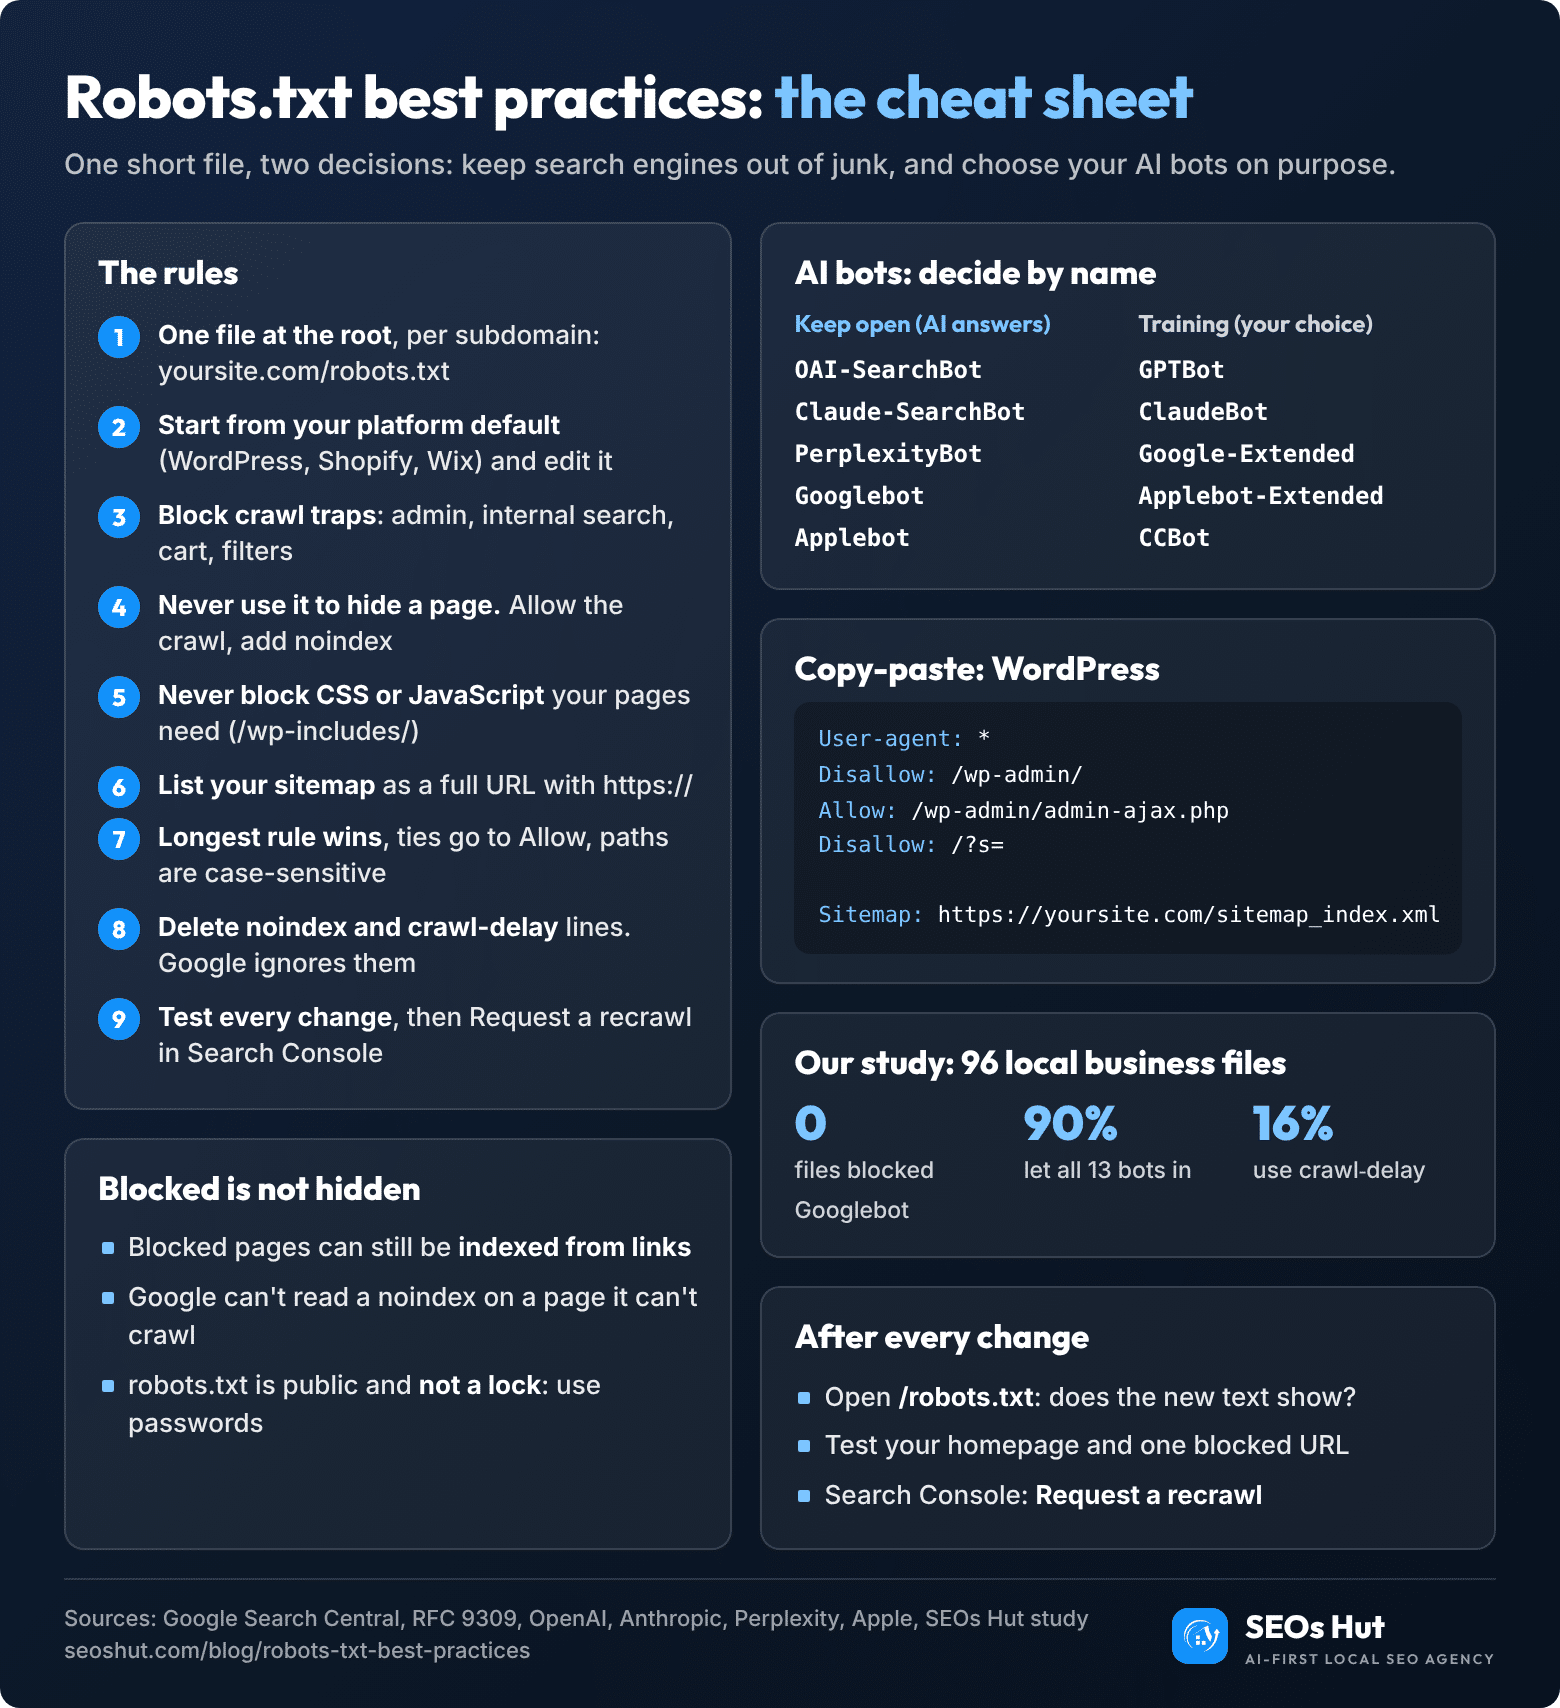
Robots.txt best practices: cheat sheet
The whole guide on one image. Save it, print it, or send it to whoever looks after your website.
FAQs
Do I need a robots.txt file?
No, but it helps. Without one, Google crawls everything, which is fine for many small sites. A short file still earns its place: it points crawlers to your sitemap and keeps them out of admin, cart and search-result URLs. What you must avoid is a file that errors, because a server error makes Google pause crawling your whole site.
Can robots.txt hurt my SEO?
Yes, one wrong line can. Disallow: / under User-agent: * stops all crawling, and blocking CSS or JavaScript folders can stop Google seeing your pages properly. Blocking a page you then noindex can keep it in results. Test every change with a tester and Search Console’s robots.txt report before you walk away.
Does robots.txt stop AI from using my content?
Partly. Blocking GPTBot, ClaudeBot, Google-Extended, Applebot-Extended and CCBot asks those companies not to use your future content for training, and the major ones say they honour it. It does not remove anything already collected, and user-triggered fetchers like ChatGPT-User or Perplexity-User may not follow it. Keep the AI search bots open if you want to appear in AI answers.
How long does it take for robots.txt changes to work?
Usually within a day. Google caches your file for up to 24 hours, and OpenAI and Perplexity both say their systems need around 24 hours to adjust. To speed Google up, open the robots.txt report in Search Console and click “Request a recrawl”. Pages that were blocked then need their own recrawl before they can show up again.
Is robots.txt legally binding?
Not by itself. The official standard describes the rules as requests that “are not a form of access authorization”, and reputable crawlers follow them voluntarily. That’s why you should never use robots.txt for security: the file is public, so listing a secret folder actually advertises it. Protect private content with a password or login instead. For legal questions, ask a lawyer.
Sources
All facts checked on 9 November 2026. Study: SEOs Hut, robots.txt files of the top Google Maps results for “plumber Phoenix AZ” and “dentist Austin TX”, 9 November 2026, read with Google-style rule matching.
- Google Search Central: How Google interprets the robots.txt specification
- Google Search Central: Robots.txt introduction and guide
- Google Search Central: Block search indexing with noindex
- Google Search Central: JavaScript SEO basics
- Google Search Central: Update your robots.txt file
- Google Search Central blog: A note on unsupported rules in robots.txt (2019)
- Google: Common crawlers (Google-Extended)
- Google Search Central: AI features and your website
- RFC 9309: Robots Exclusion Protocol (2022)
- OpenAI: Overview of OpenAI crawlers
- Anthropic: Does Anthropic crawl data from the web, and how can site owners block the crawler?
- Perplexity: Perplexity crawlers
- Apple: About Applebot
- Common Crawl: CCBot
- Bing Webmaster blog: To crawl or not to crawl (crawl-delay)
- WordPress developer reference: WP_Sitemaps::add_robots()
- Shopify developers: Customize robots.txt
- Wix Help: Editing your site's robots.txt file
- Squarespace Help: Request that AI models exclude your site
- Cloudflare blog: Control content use for AI training (2025)
Rather have someone check it for you?
A robots.txt mistake rarely travels alone. Our website audit checks your robots.txt together with indexing, sitemaps and speed, and our AI SEO services work on getting your business found and recommended in ChatGPT, Perplexity and Google’s AI answers. That is the everyday work of SEOs Hut, an AI-first local SEO agency for US and UK businesses.